
Post-incident learning
- Lesson 19
- 50 min
- Module 6: Handle incidents and handoff
Lesson 19 of 19 · MLOps and LLMOps: Operating AI in ProductionPost-incident learning
1. Define operational ownership
2. Version and reproduce the system
3. Instrument useful telemetry
4. Monitor changing behaviour
5. Release and improve safely
6. Handle incidents and handoff
What you will be able to do
Learn from an incident so that it does not happen again. Write down what happened, why the system let it happen, and what changes, each with an owner, without blaming a person.
Before you startWhat to know and to have ready
What you need to know
- “Last week”, the prompt v3 incident, from Run the live service and Service objectives.
- Runbooks and
python -m ops alerts, from Runbooks.python -m ops incidentand the fallback to a person, from Provider and dependency outages. - The gate and the canary, from Evaluation gates and Controlled rollouts.
What you need on your computer
- Your project after the last lesson, with the simulator, the API and the worker running.
- The saved telemetry in
data/telemetry/.
The pan on the stove
Section titled “The pan on the stove”A family has a small kitchen fire. A pan of oil was left on the stove, and the smoke alarm did not ring. Nobody was hurt.
The family can ask “who left the pan on?” The answer is the teenager, who went to answer the door. Everyone agrees that they must be more careful. Next month, someone else answers the door with a pan on the stove.
Or the family can ask “how could a pan burn with nobody noticing?” Then they find more: the alarm’s battery was flat, the fire blanket was in the garage, and the stove has no timer. Each of those is a change they can make, and each one protects them, whoever is cooking.
The problem: a review that blames fixes nothing
Section titled “The problem: a review that blames fixes nothing”Last week, at Larkfield, the prompt was switched from v2 to v3 for every ticket. A blaming review is quick to write: “Omar switched the prompt after the evaluation said DO NOT SHIP. Omar must follow the process.”
Look at what that review misses. In the practice replay of the incident, with real recorded answers:
- The change was a settings change. Nothing in the system stopped it, asked for a gate, or limited it to a canary.
- 186 of 1,798 tickets with prompt v3 got an answer without text, and the jobs failed quietly. Nothing sent those tickets to a person.
- The dashboard showed the accept SLI, 100.00%, as “uptime”. Nothing measured the drafts.
- The one alert that could have helped,
no-answer, already fired for one ticket of the healthy prompt, so it looked like noise.
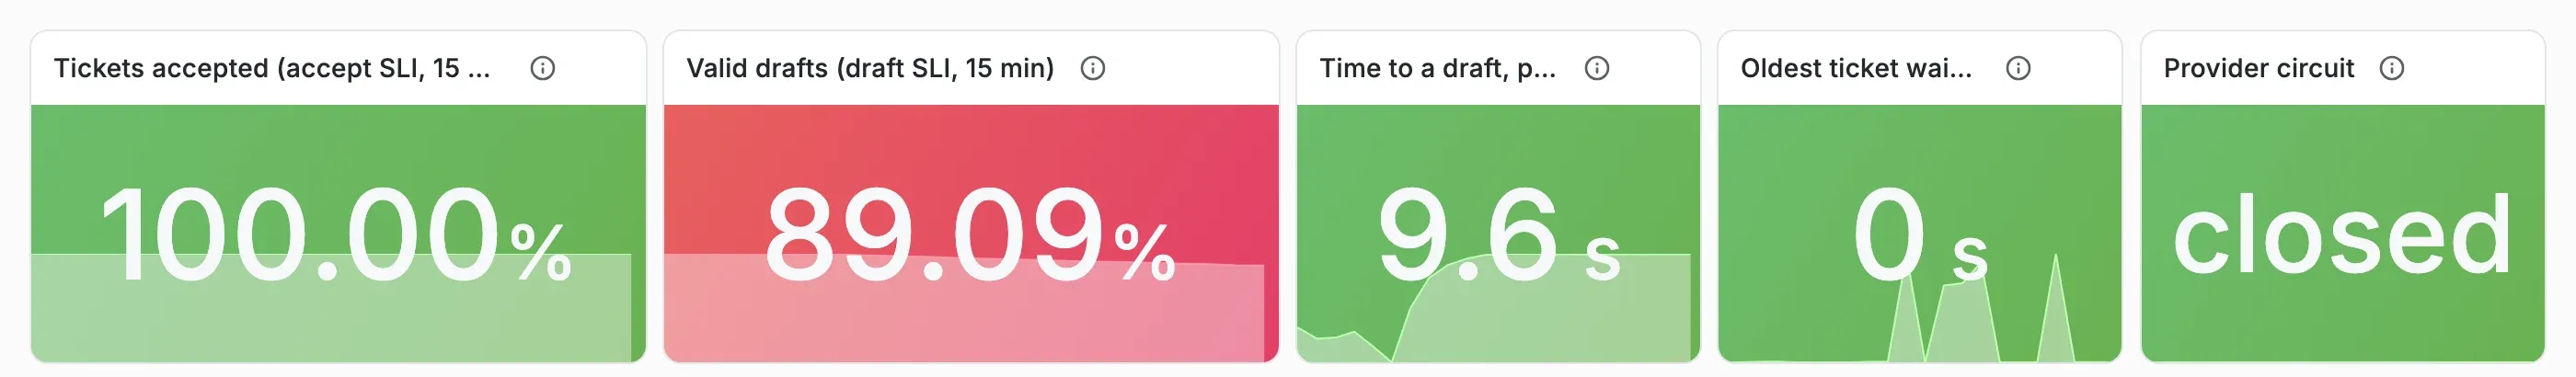
“Omar must follow the process” changes none of these. The next person under pressure to save money does the same thing, and the system lets them.
The idea: the review asks how the system let it happen
Section titled “The idea: the review asks how the system let it happen”A post-incident review is a written record of an incident: what happened, why, and what changes. It is often called a postmortem. It is blameless: it assumes that people acted sensibly with what they knew and saw at the time, and it looks for the conditions that made the mistake possible and easy to miss.
It separates two kinds of reasons:
- The cause: the change that started the harm. Here: prompt v3 makes the model reason until its token limit on some tickets, and it writes nothing.
- Contributing conditions: the weaknesses that let the cause reach customers and stay unseen. Each one is a hole that a better system would close.
A picture helps. Think of slices of Swiss cheese, one behind the other. Each slice is a defence: a gate, a fallback, a dashboard, an alert. Each has holes. Harm gets through only when the holes line up. A review finds every hole, not only the first one.

Text description of the diagram
The cause is prompt v3, which gives no text on about 10% of tickets. To reach customers, it passed four holes. It was a settings change with no gate or canary. There was no fallback for a ticket without an answer. The dashboard showed only uptime, and the no-answer alert was already noisy. The result was 10 tickets that needed a person and reached nobody. Each hole has an action. A release gets a gate and a canary (Priya, Omar). A ticket without an answer goes to a person (Amira). The main dashboard gets draft and safety SLOs (Amira, Grace). Priya reviews v2’s known case.
A tiny example: the kitchen, as a review
Section titled “A tiny example: the kitchen, as a review”Write the kitchen fire in the review’s shape, with every part visible:
| Part | The kitchen |
|---|---|
| Impact | Smoke in the kitchen; a burnt pan; nobody hurt |
| Timeline | 18:02 oil on; 18:05 doorbell; 18:12 smoke; 18:13 someone sees it; 18:14 lid on the pan |
| Cause | A pan of oil was left on a high flame |
| Contributing conditions | the alarm’s battery was flat; the fire blanket was in the garage; the stove has no timer |
| Actions, with owners | new battery and a monthly test (Dad); fire blanket next to the stove (Mum); a timer for frying (the teenager) |
| How we know it is fixed | press the alarm’s test button on the 1st of each month; the blanket is on its hook |
Look at the actions. Each one changes a thing, not a person’s attitude. Each one has an owner and a check. “Be more careful” is missing on purpose: it has no owner and no check.
The timeline also shows the gap that the review is really about. It took 7 minutes from the first smoke to the first person who saw it. In software, that gap is detection.
Larkfield’s review: PIR-001
Section titled “Larkfield’s review: PIR-001”The project’s review of last week is operations/reviews/PIR-001-prompt-v3.md. Open it. Its header:
| Severity | SEV-1 (tickets that needed a person reached nobody) |
| Owner of this review | Priya |
| People | Amira (service), Priya (prompt), Grace (customers), Omar (the change), Kwame (cost) |
| Status | actions open |
Omar is in the room, as the person who made the change. He knows best why the cheaper prompt looked safe, and the review needs that knowledge. He also owns the canary action.
Build the timeline from the telemetry
Section titled “Build the timeline from the telemetry”A timeline from memory is wrong in its details. Build it from the saved replay of the incident:
python -m ops incident data/telemetry/release-full.jsonl.gzTimeline (what happened, in order):when kind event--------- -------- ----------------------------------------------------------------------------+0.0 min practice scenario start+0.0 min practice simulator mode: normal+0.0 min practice ops rollout start 1.5.0-4fafd1 --reason practice scenario release-full+0.0 min grafana alert firing: no-answer+0.0 min release release: active 1.5.0-4fafd1+0.3 min grafana alert resolved: no-answer+3.2 min alert no-answer fired+3.3 min grafana alert firing: no-answer+5.0 min practice ops rollout start 1.5.0-767b56 --reason the cheaper prompt, for every ticket+5.0 min release release: active 1.5.0-767b56+9.7 min alert triage-slow fired+10.0 min grafana alert firing: triage-slow+10.6 min grafana alert firing: draft-fast-burn+10.7 min alert draft-fast-burn fired+10.8 min alert reviews-disagree fired+11.2 min alert cost-over-budget fired+13.8 min grafana alert firing: cost-over-budget+18.2 min alert draft-fast-burn resolved+18.3 min grafana alert resolved: draft-fast-burn+20.0 min practice scenario endThe output continues with the tickets per period; the last period’s recovery check is [ ] drafts are valid: 31 without a valid draft (first period 0). The box is empty: nothing recovered, because nobody acted.
The review’s timeline keeps the lines that matter, in plain words, and adds what the telemetry cannot know (from the review’s own table):
| When | What |
|---|---|
| +0.0 | Prompt v2 active (release 1.5.0-4fafd1). |
| +3.2 | Alert no-answer fires: prompt v2 has one recorded answer without text (practice ticket T-65450). Nobody acts: it looks like noise. |
| +5.0 | Prompt v3 becomes active for every ticket (release 1.5.0-767b56). No canary, no gate. |
| +7.9 | First safety ticket without an answer (T-65663). |
| +9.7 | triage-slow fires (rules on saved telemetry; Grafana: +9.95). |
| +10.7 | draft-fast-burn fires: SEV-2 (Grafana: +10.6). |
| +10.8 | reviews-disagree fires. |
| +11.2 | cost-over-budget fires (Grafana: +13.8). |
| +20.1 | End of the replay. Nobody rolled back: in the real incident, these alerts did not exist yet. |
The replay runs about 210 times faster than Larkfield’s real traffic. So the 15 minutes of v3 in the replay, 1,798 tickets, are about two days of real tickets: the “two days” that customers waited.
Text description of the chart
The x axis shows the 20 practice minutes; about 120 tickets finished each minute. For the first 5 minutes, with prompt v2, the line is at 0. The one exception is 1 ticket in minute 4, the known v2 case. From minute 6, after the change to prompt v3, it jumps to between 7 and 19 tickets every minute. That is about 11% on average, and it stays there until the end. The draft-fast-burn alert fires at minute 10.7.
The chart is the detection gap in one picture. The bad tickets start in the first minute after the change. The alerts follow 4.7 to 6.2 minutes later. At real speed, about 210 times slower, that is hours. That is why the review’s answer is not “a faster alert” but a canary, which limits the harm while the alerts catch up.
Causes and contributing conditions
Section titled “Causes and contributing conditions”PIR-001 lists one cause and four contributing conditions. They are the holes in the diagram above:
- The cause: prompt v3 asks for a complete, specific answer, and the model then reasons until the token limit on some tickets (25 of 271 in the evaluation; 10.3% here).
- A prompt change was made as a settings change, not a release: no manifest, no gate, no canary.
- A job without a valid answer failed quietly: the ticket stayed in the default team, with no person told (no fallback).
- The dashboard showed only the accept journey (“uptime”); nothing measured the draft journey.
- The
no-answeralert had fired before the change for one ticket of prompt v2, so a new alert looked like the same noise.
Read the wording. No item names a person. Item 2 is about Omar’s change, but it describes what the system allowed: a change that could reach every customer with one setting.
Actions with owners
Section titled “Actions with owners”| Action | Owner | Done in |
|---|---|---|
A ticket without a valid answer goes to a person (TRIAGE_FALLBACK=person) |
Amira | Module 6 |
Every prompt change is a release with a manifest, and passes the gate (ops gate) |
Priya | Modules 2 and 5 |
Every release starts as a 10% canary with rollback rules (operations/rollout.toml) |
Omar | Module 5 |
| SLOs for the draft and safety journeys, and their alerts, on the main dashboard | Amira, Grace | Modules 1 and 3 |
The no-answer alert links the ticket, and prompt v2’s known case (T-65450) is reviewed so the alert is trusted |
Priya | Module 6 |
| The provider timeout covers the slowest recorded answer, or a long answer is not retried 5 times | Kwame | open |
A good action has four properties. It changes the system, not a feeling. It has one owner by name. It says when it is done. And it can be checked. Look at the last row. One v3 recording took 12.1 seconds, longer than the 10-second timeout. So its ticket timed out on every attempt and became a dead letter, 10 times in the replay. The action is open, and the review says so. An honest “open” is better than a vague “done”.
Check that an action works
Section titled “Check that an action works”“Done” in the actions table needs evidence too. The first action, the fallback, can be checked on your own service. You make prompt v3 answer some tickets on purpose, and you check that no ticket without an answer is left alone.
-
Stop the API and the worker with Ctrl+C. Move your telemetry files to another folder, for example
telemetry/before/, so that the next count has only these tickets. Start the API and the worker again. Then make prompt v3 the active release, as a practice change. Use your own v3 ID from Evaluation gates:Terminal window python -m ops rollout start 1.5.0-422985 --by Amira --reason "practice: check the fallback with prompt v3"start: active 1.5.0-422985. The worker takes it within 5 seconds.Use the release state, not the
ASSISTANT_PROMPTsetting. Since Module 5, the worker follows the release state in the database, andRELEASE_IDoverridesASSISTANT_PROMPTtoo. A worker started withASSISTANT_PROMPT=assistant-v3would still answer with prompt v2. -
Send 40 practice tickets:
Terminal window python -m scripts.practice --tickets 40 --rate 2 --seed 11Sent 40 practice tickets in 19.5 s: 202: 40 -
Wait until the queue is empty. Look at the worker’s log. Each ticket without a valid answer has two lines like these, after the time:
WARNING ticket_api.worker [a6bfef76f157]: ticket T-500186: no valid answer, sent to a personINFO ticket_api.worker [a6bfef76f157]: job 186: succeeded (attempt 1)Read that job:
curl http://127.0.0.1:8000/v1/jobs/186, with your own job number. The end of its answer:"state":"succeeded", … "result":{"team":"other","priority":1,"needs_human":true,"draft_reply":null,"embedding_version":"embed-small-384-v1"}The ticket has no team decision and no draft, but
needs_humanis true and the priority is 1. It is first in the agents’ queue. -
Count the outcomes in your telemetry:
Terminal window python -m ops summary telemetry/ticket-api.jsonl telemetry/ticket-worker.jsonlRecords: 81 logs, 780 spans, 96 metric records, from +0.0 min to +1.1 minTicket requests: 40 (202: 40)Tickets triaged: 40 (ok: 37, sent_to_person: 3)Prompt versions: assistant-v3 40Where the answers come from: replayed 40 (100.00%)Sent to a person (needs_human): 17 (42.50%)Agents' reviews (delayed labels): 0; answers to questions: 03 of 40 tickets got no valid answer from prompt v3, about the 10.3% of last week. Each one is
sent_to_person, none is a failed job. Your counts can differ. -
Make prompt v2 the active release again, with your own v2 ID:
Terminal window python -m ops rollout start 1.5.0-5a4f87 --by Amira --reason "practice done: back to prompt v2"
The action works: a ticket without an answer now waits for a person, not for nobody. Two more things to see. First, python -m ops alerts on the same files still shows no-answer as still firing. That is right: the fallback protects the customer, but the prompt is still bad, and someone must know. Second, the old behaviour is checked by the tests: with TRIAGE_FALLBACK=none, tests/test_jobs.py expects the job to fail, as it did last week.
When to write a review, and what it costs
Section titled “When to write a review, and what it costs”Sam asks, “Do we write one of these for every alert?”
Grace answers: “No. For every SEV-1 and SEV-2, within 5 working days. A SEV-3 gets a line in the weekly notes.”
Write a review for incidents that hurt customers or burned an SLO fast. Also write one for near misses that could have: the canary that caught v3 is worth half a page. Do not write one to find who was wrong. If people expect blame, they stop reporting near misses, and the reviews dry up.
What it costs: a meeting of about an hour with the people involved, and a few hours to write. The actions themselves are the expensive part. A review whose actions never close is a document, not learning.
Common mistakes
Section titled “Common mistakes”Common mistake
The action is 'be more careful'
Symptom: the actions table says “Omar will check the evaluation before changing prompts”, or “Everyone: take more care with releases”.
Cause: the review stopped at the person. An action about attention has no check, and it fails the next time someone is busy.
Fix: ask “what would stop this, whoever made the change?” Here: a gate that refuses the release, and a canary that limits it. Each has an owner and a test.
Module practice: a tabletop exercise
Section titled “Module practice: a tabletop exercise”This module’s practice task: run a tabletop exercise for an unavailable provider or a faulty model release. A tabletop exercise is a practice incident on paper. A facilitator reads out what happens, minute by minute, and the team says what they do, with the runbook open. Nothing is broken for real. You test the people and the runbooks, not the code. First, a worked example with every step visible. Then you run one yourself.
Worked example: a faulty release, with the replay of last week
Section titled “Worked example: a faulty release, with the replay of last week”Priya facilitates. Amira is on call, Grace speaks for customers. The saved replay gives the facts. Each “inject” is a line that the facilitator reads, from python -m ops alerts and ops incident on release-full.jsonl.gz:
| Inject (practice minute) | The facilitator says | What the team answers, with the runbook bad-release.md |
Found |
|---|---|---|---|
| +3.2 | “no-answer fires, SEV-2.” |
Amira runs triage step 1: one no-answer, release 1.5.0-4fafd1, practice ticket T-65450, the known case. She notes it, and does not page Priya at night. | The runbook has no line for the known case. Action: add it, with the ticket ID. |
| +5.0 | “Someone switches the active release to 1.5.0-767b56 for every ticket.” | Nobody sees it: no alert fires on a release change. | Action: the release-change event goes to the team’s chat. |
| +10.7 | “draft-fast-burn fires, SEV-2.” |
Triage step 1: release 1.5.0-767b56 has 10.3% no-answers, v2 has one. Step 2: it changed at +5.0. Mitigation: ops rollout rollback. |
It works, but 5.7 minutes after the change. |
| +10.9 | “Grace asks: did any safety ticket get no answer?” | The runbook says to find tickets with outcome no_answer since the release, safety first. Amira does not know how to list them. |
Action: add the command to the runbook. |
| after rollback | “How do you know it is over?” | Recovery checks: the canary line of ops canary and the last period of ops incident must show no new no-answer above v2’s known case. |
The checks work. |
Result: three actions for the runbook, each with an owner (Priya for the known case and the safety list, Amira for the release-change event). The exercise took 30 minutes and broke nothing.
Your turn: a provider outage of 30 minutes
Section titled “Your turn: a provider outage of 30 minutes”Run a tabletop exercise of the provider runbook (operations/runbooks/provider-outage.md). Use the saved outage run as your facts. But tell the team that the outage lasts 30 minutes at Larkfield’s real rate, not 5 practice minutes.
- Write five injects, with a practice minute and a sentence each. Take the first three from
python -m ops incident data/telemetry/outage.jsonl.gz. Make the last two up, and label them “constructed”: one about a customer, and one about a safety ticket. - For each inject, write what the runbook tells the person on call to do, and who acts.
- List each gap that you found in the runbook as an action with an owner.
- Write the recovery checks that would close the incident, each with the command that gives its number.
Worked solution
Injects and answers (the first three from the saved run; the times as they would be at the start of a real outage):
| Inject | Runbook answer | Who |
|---|---|---|
+0.6: provider-circuit-open fires, SEV-2 |
Triage: is it the provider? curl http://127.0.0.1:8300/admin/stats in practice, the provider’s status page in real life. Are tickets lost? No: GET /v1/queue grows, accept SLI 100%. Mitigation: do nothing to the workers. |
Amira |
+3.1: drafts-late fires, SEV-2; GET /v1/status says “delayed” |
The website shows the delayed message automatically. Grace’s team reads the queue for safety words. | Amira, Grace |
| +5.0: still down | Wait: the breaker probes every 30 seconds. Do not raise retries or the timeout. | Amira |
| +15, constructed: “A customer calls: I sent my ticket twice, will I get two replies?” | The status said not to send it again. Two tickets exist; the agents merge them. Gap: the runbook has nothing about duplicate tickets. | Grace |
| +20, constructed: “A ticket says: smoke from the charger.” | It waits in the queue like any other. The runbook says agents read the queue by hand, but not how. Gap: no command lists queued tickets with safety words. | Grace’s team |
| +30 | The draft SLO breaks for the first tickets from about +9 minutes, as the last lesson computed. SEV-2 stays; escalation after 15 minutes: Kwame asks the provider for a time to recovery; after 30, Grace updates the help page. | Kwame, Grace |
Actions: a runbook line for duplicate tickets (Grace); a command or a dashboard panel that lists queued tickets whose text has safety words, run by the agents (Amira); the provider’s support contact and contract number in the runbook (Kwame); a decision record on whether a second provider is worth its evaluation cost after a 30-minute outage (Kwame, open).
Recovery checks, each with its number:
- breaker closed: the worker’s log, or the timeline of
python -m ops incident; - queue drained:
GET /v1/queue,oldest_queued_secondsunder 120; - no dead letters:
GET /v1/queue,dead_letter0, or each one retried; - drafts valid and on time: the last full period of
ops incident; - customers told it is over:
GET /v1/statussays ok, and Grace removed the help-page note.
Completion check: restore a known-good state, and prove it
Section titled “Completion check: restore a known-good state, and prove it”Restore Larkfield’s service to its known-good release, and list the evidence that confirms the recovery. Use your own service for the restore, and the saved canary run for the evidence of a full rollback.
- Make release
1.5.0-4fafd1(prompt v2) the active release withpython -m ops rollout, with a reason. - Show that this release is what you think it is: that its manifest matches the files.
- Show the release history, with who made the change and why.
- On the saved canary run, list the numbers that confirm that customers got the good release again after the rollback.
Worked solution
python -m ops rollout start 1.5.0-4fafd1 --reason "known-good release after the tabletop" --by Amirastart: active 1.5.0-4fafd1. The worker takes it within 5 seconds.python -m ops release verify 1.5.0-4fafd1Release 1.5.0-4fafd1 matches the files here (code, prompt, migrations).python -m ops rollout historywhen action state after by reason-------- ------ ------------------- ----- -------------------------------------------+0.0 min start active 1.5.0-5a4f87 Amira prompt v2 on the Module 5 code+1.4 min start active 1.5.0-422985 Amira practice: check the fallback with prompt v3+2.6 min start active 1.5.0-5a4f87 Amira practice done: back to prompt v2+2.8 min start active 1.5.0-4fafd1 Amira known-good release after the tabletopYour history also has the changes of Controlled rollouts, so it is longer, and your times differ. The last row is the restore.
The restore alone proves nothing about customers. The evidence is on the tickets after the change. In the canary run of Module 5, the last line of python -m ops canary data/telemetry/canary.jsonl.gz is:
After the last release change (+7.3 min: active 1.5.0-4fafd1, canary None): 1,533 tickets, 2 without text, US$0.341 per 1,000, triage p95 5.17 s, canary tickets 0The evidence list:
- Canary tickets 0 after the rollback: no customer got prompt v3 any more.
- 2 without text in 1,533: the rate of prompt v2’s known case, not v3’s 10%.
- US$0.341 per 1,000 and a triage p95 of 5.17 s: v2’s values (US$0.340 and 5.18 s in the same run), not v3’s (0.479 and 7.86).
- The manifest matches the files (
ops release verify): the release that answers is the one that passed the gate. - The history records who changed the release, when, and why: the start of the next review’s timeline.
A good answer says that each number is compared with a value from before the incident. “The alert stopped” is not on the list.
Knowledge check
Section titled “Knowledge check”Check your understanding
What is the difference between the cause and a contributing condition? Give one of each from last week.
Show the answer
The cause is the change that started the harm: prompt v3. It makes the model reason to its token limit and write nothing on about 10% of tickets. A contributing condition is a weakness that let the cause reach customers or stay unseen. For example, a prompt change could go live as a settings change, without a gate or a canary. Removing the cause fixes this incident. Removing the conditions protects against the next cause too.
Does your answer have the main points of ours?
Sign in and enroll in the course to save your answers. Every check counts toward the certificate.
Check your understanding
Rewrite this sentence from a draft review without blame, and say why it matters: 'Omar ignored the evaluation and broke the help desk.'
Show the answer
For example: “The prompt was switched for every ticket as a settings change. The evaluation’s DO NOT SHIP decision was in an experiment record, but nothing in the release path checked it.” The facts are the same. The new sentence points at what the system allowed, so the action is a gate that reads the decision, not a warning to Omar. And Omar can explain what made the change look safe, which the review needs.
Does your answer have the main points of ours?
Sign in and enroll in the course to save your answers. Every check counts toward the certificate.
Check your understanding
Predict: Larkfield had run prompt v3 as a 10% canary with the fallback to a person. What would the review's impact line say?
Show the answer
About 1 in 10 tickets would use v3, and the canary would roll back within minutes. In the canary run, 22 canary tickets came before the rollback: 3 without text, none a safety ticket. With the fallback, those 3 tickets would go to a person instead of nobody. So the impact would be a few slower tickets, no ticket left alone, and no SEV-1: a near miss, worth half a page of review.
Does your answer have the main points of ours?
Sign in and enroll in the course to save your answers. Every check counts toward the certificate.
Recap
This module prepared the service for the day something breaks. Now you can:
- Write a runbook for each alert: detection, triage, mitigation, escalation and recovery checks, with a command or a panel in each step. Test the alert rules on saved runs with
python -m ops alerts, and spot alerts that cry wolf. - Plan a provider outage: queued work that keeps every ticket, and a breaker that spends no attempts. Add a fallback to a person, and an honest customer status from
GET /v1/status. Estimate how long an outage can last before the draft SLO breaks. - Verify a recovery with a checklist of numbers from
python -m ops incidentand the API, not with the state of an alert. - Write a blameless post-incident review: a timeline from the telemetry, the cause, the contributing conditions, and actions with owners and checks. Run a tabletop exercise to test the runbooks.
Reset. If your project is broken, copy the snapshot end-of-m06, keep your .env, and run python -m scripts.load --reset, as the snapshots README shows.
Next, the case studies apply the course to public data and a public incident. Then the final assignment asks for your own operations pack.