
Service objectives
- Lesson 3
- 55 min
- Module 1: Define operational ownership
Lesson 3 of 19 · MLOps and LLMOps: Operating AI in ProductionService objectives
1. Define operational ownership
2. Version and reproduce the system
3. Instrument useful telemetry
4. Monitor changing behaviour
5. Release and improve safely
6. Handle incidents and handoff
What you will be able to do
“Up 99.9% of the time” was true last week, and customers still waited for nobody. Turn each thing that customers and the help desk need into a number with a target, so that “working” means the same thing to everyone. Then compute how much failure each target allows.
Before you startWhat to know and to have ready
What you need to know
- Run the live service and What is operated: the triage step, the saved telemetry and
python -m ops. - Percentiles (p95), from Latency and capacity.
- Optional: Quality attributes in the system design course also writes SLOs, for a design that is not built yet.
What you need on your computer
- Your project at the snapshot
end-of-m01, with the saved telemetry indata/telemetry/. No Docker.
The bus company’s promise
Section titled “The bus company’s promise”A city bus company cannot promise that every bus is on time. Traffic, snow and a broken door make some buses late. So the company makes a promise that it can keep and check: “95 of every 100 buses leave within 3 minutes of the timetable, counted every month.”
Look at what that promise does. It names what passengers care about: leaving on time, not “the buses are running”. It says how to count a good bus: within 3 minutes. It gives a target below 100%, and a period. And it gives the company a budget: out of 10,000 buses a month, 500 can be late. Suppose 400 are late by the 20th of the month. The manager knows that the budget is almost gone, and stops the road works that make buses late.
The help desk needs the same kind of promise.
The problem: the wrong number was green
Section titled “The problem: the wrong number was green”Here are the same five panels as in Run the live service, during the normal week this time:
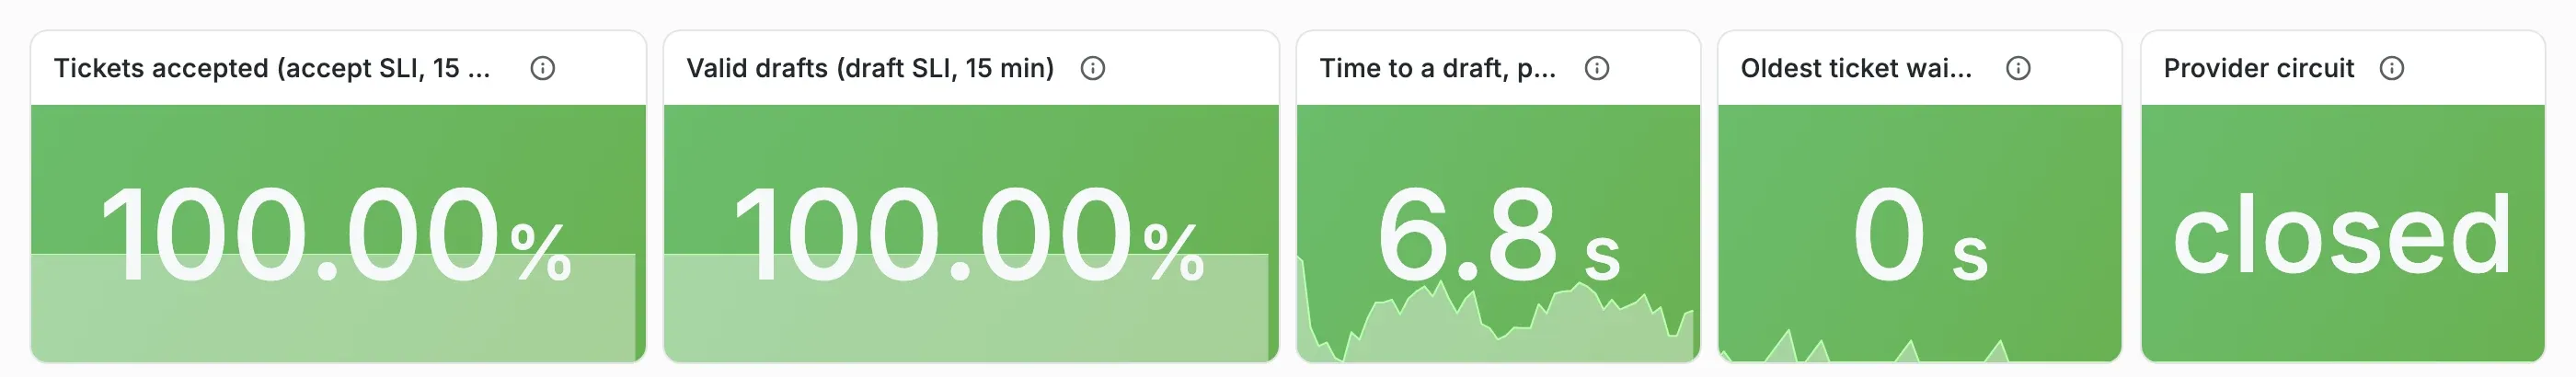
In the normal week, the first panel said 100.00%. Last week, during the prompt v3 change, it also said 100.00%. The number that everyone watched could not tell a good week from a bad week. It measured whether the API accepted a ticket. Customers do not want a ticket to be accepted. They want an answer, and a safety ticket must reach a person.
The second panel, valid drafts, did change: 100.00% in the normal week, 89.09% last week. Somebody had built that panel. But nobody had said what number it should show, so nobody knew that 89.09% was bad.
The idea: journeys, indicators and objectives
Section titled “The idea: journeys, indicators and objectives”Start from the people, not from the service. A user journey is one thing that a user tries to do, from start to end. Examples: “a customer sends a ticket”, “the help desk gets a decision and a draft”. Then, for each journey, two words:
- A service level indicator, or SLI, is a measured share of good events: good events ÷ all events. For the draft journey: tickets that got a valid triage within 10 minutes ÷ all accepted tickets. It indicates the level of the service that users get.
- A service level objective, or SLO, is a target for an SLI, over a window. For the draft journey: 99% of tickets, counted over a week of tickets. It is the objective for that level. Like the bus company’s 95%, it is a decision, not a measurement.
The SLI is the bus counter at the stop. The SLO is the promise on the company’s website.
A tiny example: ten tickets
Section titled “A tiny example: ten tickets”Ten customers send a ticket. Here is what happens to each one:
| Ticket | Accepted (202)? | Valid triage? | Time to a draft | Good for “accept”? | Good for “draft”? |
|---|---|---|---|---|---|
| 1–8 | yes | yes | 3 to 6 s | yes | yes |
| 9 | yes | no: answer without text | – | yes | no |
| 10 | yes | yes | 4 s | yes | yes |
The accept SLI is 10 good ÷ 10 = 100%. The draft SLI is 9 good ÷ 10 = 90%. The same ten tickets give two different numbers, because the two journeys ask different questions. Ticket 9 is a success for the API and a failure for the customer.
With a draft SLO of 99%, the target allows 1% of 10 = 0.1 bad tickets. One bad ticket is ten times what the target allows. That ratio has a name, the burn rate, and you will meet it below.
Larkfield’s objectives
Section titled “Larkfield’s objectives”Amira, Priya and Grace wrote one SLO for each journey in operations/slos.toml. Here is the draft journey’s block:
[[slo]]id = "draft"journey = "The help desk gets a decision and a draft reply"sli = "accepted tickets with a valid triage (team, needs a person, draft) within 10 minutes"threshold_seconds = 600target = 0.99owner = "Amira"The six journeys, and why each target:
| SLO | Journey | Good event | Target | Why this target |
|---|---|---|---|---|
accept |
A customer sends a ticket | the API accepts it (202); the caller’s own 4xx do not count | 99.9% | Losing a ticket is serious, and accepting is simple. |
draft |
The help desk gets a decision and a draft | a valid triage within 10 minutes | 99% | Even the good prompt v2 has one answer without text in 679. |
quality |
The decision is right | team and needs-a-person agree with the agent’s review | 90% | The healthy prompt v2 agrees with the agents about 94% of the time; 90% leaves room. |
safety |
A ticket that needs a person reaches a person | the assistant sent it to a person | 100% | No budget. One miss is a SEV-1 incident. |
answer_time |
A customer asks a question | answered within 3 s | 95% | The website waits for this answer. |
answer_sources |
An answer quotes current documents | every source is the current version | 99% | An old rule in an answer misleads a customer. |
Two of them, quality and safety, depend on agents’ reviews, which arrive later. They are delayed: you know the answer only after a person checked the ticket. Delayed labels handles this.
There is also a budget: at most US$0.40 per 1,000 tickets for the AI calls. It is not an SLO. Customers do not feel it, but Kwame does.
The window is counted in tickets. A week at Larkfield is 822 tickets a day × 7 = 5,754 tickets. The practice scenarios send a week of tickets in 48 minutes. Because the window is in tickets, the same numbers hold in a practice run and in real life.
The error budget
Section titled “The error budget”The bus company’s 95% left a budget of 500 late buses a month. An SLO does the same. The error budget is the number of bad events that the target allows in the window:
error budget = (1 − target) × all events in the window
For the draft SLO over one week: (1 − 0.99) × 5,754 = 57.5 tickets. Amira can spend that budget: on a risky release, on a provider’s slow day, on the “spark plug” answer. When it is gone, the users have had more failure than the promise allows, and releases stop until the service is back within its SLO.
The speed of spending also matters. The burn rate compares the share of bad events with the share that the target allows:
burn rate = (bad ÷ all) ÷ (1 − target)
A burn rate of 1 uses the budget at exactly the planned speed: it is gone at the end of the window. A burn rate of 10 uses it ten times faster: a week’s budget is gone in less than a day.
Now let the ops tool do the counting for the normal week:
python -m ops slo data/telemetry/normal-week.jsonl.gz5,754 tickets, +0.0 min to +48.0 min; objectives from operations/slos.tomlSLO SLI (good/all) target budget bad used burn owner-------------- --------------------- ------ ------ --- ---- ---- -----accept 100.00% (5,754/5,754) 99.9% 5.8 0 0% 0.00 Amiradraft 99.93% (5,750/5,754) 99.0% 57.5 4 7% 0.07 Amiraquality * 94.32% (1,478/1,567) 90.0% 156.7 89 57% 0.57 Priyasafety * 100.00% (320/320) 100.0% 0.0 0 n/a n/a Graceanswer_time 100.00% (470/470) 95.0% 23.5 0 0% 0.00 Amiraanswer_sources 100.00% (470/470) 99.0% 4.7 0 0% 0.00 Tomás* from agents' reviews, which arrive later (delayed labels)Cost: US$0.341 per 1,000 tickets (budget US$0.40)Read the draft line from left to right. The SLI is 5,750 good of 5,754: 99.93%. The target is 99%, so the budget is 57.5 tickets. Four were bad: the “spark plug” answer, drawn four times. They used 7% of the budget, at a burn rate of 0.07. The quality budget is counted on the reviewed tickets only: 10% of the 1,567 reviews is 156.7, because its target is 90%. Every SLO is met, and the cost is under its budget. This is a good week.
Before you look at last week, try the targets yourself.
Explore
How much failure does each target allow?
Predict first: Does a target of 99.9% leave more room for failure than 99%, or less? How many of the normal week's 4 bad tickets fit in each?
- Budget for one week (5,754 tickets)
- 57.5
- Normal week: bad tickets
- 4 of 57.5
- "Last week": budget gone at
- ticket 1,098
1% of 5,754 tickets can fail: a budget of 57.5 tickets a week. The normal week had 4 bad tickets: 7% of a budget of 57.5. "Last week" used up the whole budget at ticket 1,098, 497 tickets after prompt v3 went live. After 2,400 tickets it had 197 bad tickets: 3.4 times the budget.
- Normal week (recorded)
- "Last week" (replay)
Text description of the explorer
The explorer has one control, the target of the draft SLO: 99%, 99.5%, 99.9% or 99.99%. The readout gives the budget for one week and the normal week’s bad tickets. It also gives the ticket at which the replay of last week used up the whole budget. The chart’s x axis is the tickets since the start of the week, from 0 to 5,754. The y axis is the budget left, in tickets. The normal week’s line starts at the budget and steps down four times. The line of last week starts at the same height and steps down once at ticket 346 (the “spark plug” answer). It falls steeply after ticket 601, where prompt v3 went live.
At 99%, the budget is 57.5 tickets. The normal week uses 4 of them (7%). Last week used up the budget at ticket 1,098, 497 tickets after the switch. It ended with 197 bad tickets, 3.4 times the budget. At 99.5%, the budget is 28.8, and last week ran out at ticket 848. At 99.9%, the budget is 5.8 tickets. The normal week uses 70% of it, and last week ran out 36 tickets after the switch. At 99.99%, the budget is 0.6 of a ticket: one bad ticket breaks it. Even the normal week breaks it, at ticket 2,433, and last week broke it at ticket 346, before prompt v3 went live.
A higher target leaves less room, not more. 99.9% sounds only a little better than 99%, but its budget is ten times smaller. And at 99.99%, the good prompt v2 breaks the SLO on its own, with one recorded answer. A target that the healthy service cannot meet is not a promise. It is an alarm that never stops, and people learn to ignore it.
Last week, measured against the objectives
Section titled “Last week, measured against the objectives”python -m ops slo data/telemetry/release-full.jsonl.gz2,400 tickets, +0.0 min to +20.1 min; objectives from operations/slos.tomlSLO SLI (good/all) target budget bad used burn owner-------------- --------------------- ------ ------ --- --------- ---- -----accept 100.00% (2,400/2,400) 99.9% 2.4 0 0% 0.00 Amiradraft 91.79% (2,203/2,400) 99.0% 24.0 197 821% 8.21 Amiraquality * 86.68% (911/1,051) 90.0% 105.1 140 133% 1.33 Priyasafety * 98.08% (204/208) 100.0% 0.0 4 no budget n/a Graceanswer_time n/a (0/0) 95.0% 0.0 0 n/a n/a Amiraanswer_sources n/a (0/0) 99.0% 0.0 0 n/a n/a Tomás* from agents' reviews, which arrive later (delayed labels)Cost: US$0.440 per 1,000 tickets (budget US$0.40, OVER)Now the table tells the story that the uptime number hid:
- accept is still 100%. The API never failed.
- draft is 91.79%: 197 bad tickets against a budget of 24 for these 2,400 tickets. The budget is used 8 times over, at a burn rate of 8.21.
- quality is below its target: the decisions that agents checked agree less often.
- safety has 4 misses in 208 reviewed tickets that needed a person. With a 100% target, there is no budget: each miss is an incident. (Ten such tickets reached nobody; only 4 of them had been reviewed when the file ended.)
- cost is over its budget: US$0.440 per 1,000 tickets.
answer_timeandanswer_sourcesshown/a (0/0): nobody asked a question in this scenario. No data is not the same as good data.
The chart shows the same thing over time, one point per 100 tickets:
- Accept SLI
- Draft SLI
- Draft SLO (99%)
Text description of the chart
The x axis counts the 2,400 tickets of last week, and each point is a block of 100 tickets. The accept SLI is a flat line at 100% from start to end. The draft SLI is at 99% to 100% for the first 600 tickets, with prompt v2. After ticket 601, where prompt v3 went live, it falls to between 85% and 93% in every block. That is far below the dashed line of its 99% SLO.
Severity levels: how bad is it?
Section titled “Severity levels: how bad is it?”An SLO tells you that something is wrong. It does not tell you whether to wake someone up at night. For that, Larkfield writes severity levels in the same file. A severity level is a class of incident, with the response that it gets:
| Level | Meaning | Response |
|---|---|---|
| SEV-1 | Customers can be harmed, or many cannot be served: a safety ticket not sent to a person, tickets lost, another customer’s data shown, or no ticket accepted. | Page the person on call at once, at any hour. Grace tells the affected customers within 1 hour. |
| SEV-2 | An SLO burns fast: its budget would be gone within one day of tickets (822); or a release makes answers worse for many customers. | Page the owner during the day, within 30 minutes. Stop releases until it is fixed. |
| SEV-3 | An SLO burns slowly, or the cost is over its budget. | A ticket for the owner, the next working day. |
| SEV-4 | A single failure; no SLO is at risk. | Note it for the weekly review. |
“Gone within one day of tickets” is a burn rate you can compute. The budget is planned for 5,754 tickets. If it goes in 822 tickets, the burn rate is 5,754 ÷ 822 = 7. So any burn rate of 7 or more is SEV-2.
Apply it to last week. The draft SLO burned at 8.21, so that alone is SEV-2. But the safety SLO had misses: tickets that needed a person reached nobody. That is SEV-1. The incident was SEV-1 for two days, and the dashboard was green.
When to use SLOs, and what they cost
Section titled “When to use SLOs, and what they cost”Omar asks, “Why not 100% for everything? We want the best service.”
Grace answers: “Then every failure is an emergency, and we never ship anything new. A target below 100% says how much failure we accept, so we can spend it on change. Safety is the one place where we accept none.”
Use SLOs for the journeys that users would complain about, and keep them few: Larkfield has six. Each one costs work. Someone must measure it, look at it, and act when it burns. A journey without an owner is a dashboard panel, not an SLO. Choose targets from what the service really does, as the 99% for drafts: v2’s own answers without text must fit in the budget. Change a target only on purpose, with the people who depend on it.
Your turn
Section titled “Your turn”Grace wonders whether the draft target should be 99.5%. Use last week’s numbers from ops slo: 197 bad tickets of 2,400. Compute the budget for those 2,400 tickets, the share of the budget used and the burn rate. Which severity level is it? Then check your numbers by editing target in operations/slos.toml and running ops slo again. Put the target back to 0.99 afterwards.
A worked solution
The budget is (1 − 0.995) × 2,400 = 12 tickets. The share used is 197 ÷ 12 = 16.4, so 1,642%. The burn rate is (197 ÷ 2,400) ÷ 0.005 = 0.0821 ÷ 0.005 = 16.42. That is more than 7, so the draft SLO alone makes it SEV-2; the safety misses still make the incident SEV-1. With target = 0.995, ops slo prints 12.0 in the budget column, 1642% and 16.42 for the draft line. A stricter target does not change what happened. It changes how loudly the numbers say it.
Common mistakes
Section titled “Common mistakes”Common mistake
Two numbers for the same SLI: 89.09% in Grafana, 91.79% in ops
Symptom: the Grafana panel for last week shows a draft SLI of 89.09%. ops slo on the same telemetry says 91.79%. One of them seems wrong.
Cause: they count different windows. The panel counts the last 15 minutes of the run, when prompt v3 was live for every ticket. ops slo counts the whole file, including the 600 tickets with prompt v2 at the start.
Diagnose: always read the window next to the number. The panel’s title says “15 min”. ops slo prints its window on the first line: 2,400 tickets, +0.0 min to +20.1 min.
Fix: compare numbers over the same window. python -m ops slo FILE --last 822 counts only the last 822 tickets, one day of Larkfield’s tickets. On last week, it gives a draft SLI of 89.54% and a burn rate of 10.46.
Common mistake
n/a read as fine
Symptom: in last week’s table, answer_time and answer_sources show n/a (0/0). A summary that says “4 of 6 SLOs failed” counts them as met.
Cause: no event means no measurement. Nobody asked a question in that scenario, so there is nothing to judge.
Fix: report “no data” as its own state. If a journey that should have traffic shows 0/0 in production, that is a problem too: a broken feature or broken telemetry.
Knowledge check
Section titled “Knowledge check”Check your understanding
Explain how a service can be available but still fail its users. Use last week's two SLIs.
Show the answer
Availability measured one journey: a customer sends a ticket. The accept SLI was 100.00% (2,400 of 2,400): every ticket was saved. But the help desk’s journey failed. The draft SLI was 91.79% (2,203 of 2,400): prompt v3 gave 186 answers without text, and 10 tickets became dead letters. The API had already answered 202, so it could not see the failure. Ten tickets that needed a person reached nobody, a SEV-1. A service is “working” only for the journeys that you measure.
Does your answer have the main points of ours?
Sign in and enroll in the course to save your answers. Every check counts toward the certificate.
Check your understanding
Predict: the draft SLO's target goes from 99% to 99.9%. What happens to the weekly error budget, and does the normal week still meet the SLO?
Show the answer
The budget becomes ten times smaller: (1 − 0.999) × 5,754 = 5.8 tickets instead of 57.5. The normal week’s 4 bad tickets still fit (70% of the budget), so it still meets the SLO, but with little room left. At 99.99%, the budget is 0.6 of a ticket, and the healthy prompt v2 breaks it with one recorded answer without text.
Does your answer have the main points of ours?
Sign in and enroll in the course to save your answers. Every check counts toward the certificate.
Check your understanding
Practical check: run ops slo on last week with --last 822. What are the draft SLI and its burn rate, and which severity level does the burn rate alone give?
Show the answer
python -m ops slo data/telemetry/release-full.jsonl.gz --last 822 prints 822 tickets, +13.2 min to +20.1 min and the draft line 89.54% (736/822), budget 8.2, bad 86, burn 10.46. A burn rate of 7 or more uses a week’s budget within one day of tickets, so it is SEV-2. The safety line, 95.83% (46/48), has misses, so the incident is SEV-1.
Does your answer have the main points of ours?
Sign in and enroll in the course to save your answers. Every check counts toward the certificate.
Recap
- A user journey is one thing a user tries to do. An SLI is the share of good events in it; an SLO is the target for that share over a window. Larkfield has six SLOs and a cost budget, in
operations/slos.toml. - The error budget is (1 − target) × events: 57.5 tickets a week for drafts at 99%. The burn rate says how fast it goes; 7 or more is SEV-2.
- Last week: accept 100.00%, draft 91.79% (burn 8.21), safety misses: a SEV-1 behind a green “uptime”.
- A higher target leaves less room. A target that the healthy service cannot meet is noise.
Next, you give every part and every SLO an owner, and write who is called first.
Next: Ownership and support