
Run the live service
- Lesson 1
- 45 min
- Module 1: Define operational ownership
Lesson 1 of 19 · MLOps and LLMOps: Operating AI in ProductionRun the live service
1. Define operational ownership
2. Version and reproduce the system
3. Instrument useful telemetry
4. Monitor changing behaviour
5. Release and improve safely
6. Handle incidents and handoff
What you will be able to do
Larkfield’s ticket service is live, and its assistant now triages every ticket. Run the service on your computer, send it practice tickets, and read a saved week of its telemetry with the course’s ops tool.
Before you startWhat to know and to have ready
What you need to know
- The ticket service
ticket-apifrom Scaling APIs and AI Workloads: the simulated AI provider, the job queue and the worker from Job lifecycle, andpython -m scripts.queue_watchfrom Backpressure. - The help desk’s assistant from Evaluating and Testing AI Systems: prompt v2 (the baseline), prompt v3 (the candidate), and the decision DO NOT SHIP for v3 from Trade-offs and regressions.
- Release versions from CI/CD, Testing and Safe Releases, and the database from Databases and Storage for AI Applications.
What you need on your computer
- Python 3.12 or later, Docker Desktop, VS Code and a terminal.
- About 200 MB of free disk space for the virtual environment, and about 15 MB for the saved telemetry. No account, no key and no money.
You start from the snapshot start: the project at the end of the scaling course, unchanged. If you have your own ticket-api from that course, keep it under another name.
Without Docker, you cannot run the service. You can still do the last part of this lesson, Read a saved week, and every later analysis in the course. It needs only Python.
A new job: the night shift
Section titled “A new job: the night shift”Imagine that you start a new job as the night manager of a small hotel. The hotel is open, and nobody will close it so that you can learn.
On your first night, you change nothing. You walk through the building once. You watch one guest check in, from the door to the room. Then you read the log book of last week.
That is this lesson. The ticket service is the hotel. You run it once on your computer. You follow one ticket from the website to the help desk. Then you read a log of a whole week.
Larkfield’s service is live
Section titled “Larkfield’s service is live”You know Larkfield’s help desk from the earlier courses. In Scaling APIs and AI Workloads, Amira made the ticket service handle Black Friday. In Evaluating and Testing AI Systems, Priya tested the help desk’s assistant. Now the two meet: the ticket service is live for real customers, and the assistant triages every new ticket.
The people are the same: Amira, the developer, guides you; Priya owns the assistant’s quality; Grace leads the help desk; Mei, Kwame, Omar, Tomás and Sam are here too.
The dashboard says that the service is up 99.9% of the time. But last week, customers waited two days for answers on safety tickets, and nobody noticed. Here is the service’s dashboard during that week:
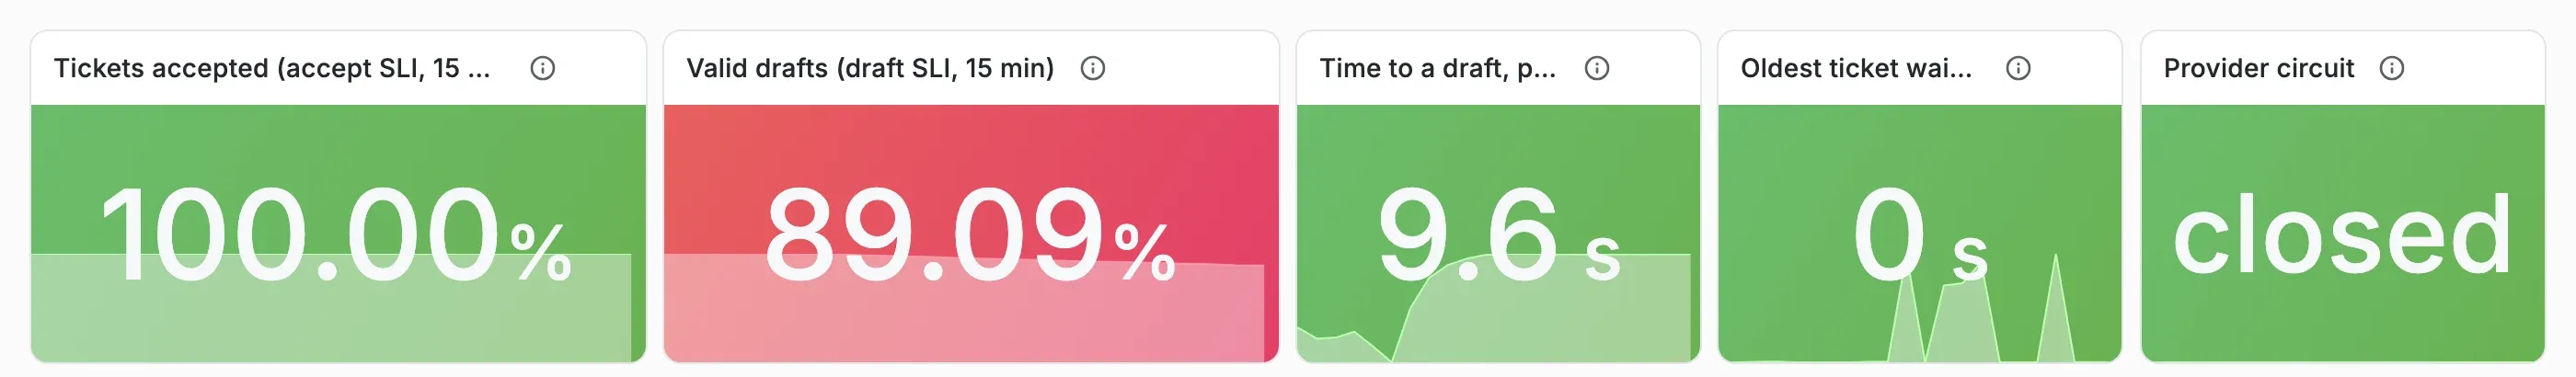
The first panel is the “uptime” that everyone watched: 100% of tickets accepted. The second panel tells another story: only 89.09% of the tickets got a valid answer from the assistant. The others were saved, and then they waited for nobody. One customer wrote that the handle of a frying pan was cracked and very hot, and asked whether it was safe.
What happened? Omar’s team switched the assistant to prompt v3 with one setting, for every ticket. The evaluation course had said DO NOT SHIP for v3. Nobody connected the setting change with the empty answers.
Grace asks the question of this course: “How would we know that the assistant is failing our customers, before they tell us?”
Making a model work in production, and keeping it working, has a name: MLOps (machine learning operations). LLMOps is the same work for applications built on large language models, with their own parts: prompts, provider models, retrieval indexes. In this course, you do both for one service.
This is a practice replay. The course caused the incident on purpose, on the real service, and the assistant’s answers in it are real recorded answers. You read its numbers at the end of this lesson.
What changed in the service: the triage step
Section titled “What changed in the service: the triage step”In the scaling course, the worker asked the provider two questions about each ticket: classify (team and priority) and draft a reply. Now one request does both jobs. It is exactly the evaluation course’s request: the same prompt files, the same policy, the same output schema and the same token limit. This step is the triage: the first sorting of a ticket, as in a hospital’s emergency room.
The assistant gives three things for each ticket:
- The team: delivery, returns, payment, warranty or account. These are the evaluation course’s five teams. Tickets saved before keep their old team names.
- Needs a person (
needs_human): true when Grace’s rules say that a person must handle the ticket, for example a safety problem. - A draft reply, which an agent checks before it is sent.
The assistant gives no priority, so the service sets it: priority 1 when a person must handle the ticket, priority 2 otherwise. The assistant reads the ticket’s body, the customer’s own message. The subject is a short title that the website makes from the first sentence.

Text description of the diagram
The customer sends a ticket. The API saves it with a job in PostgreSQL and answers 202 Accepted at once, as in the scaling course’s queue design. Later, the worker takes the job and sends one triage request to the provider. About 3 seconds later, the answer comes back with the team, the decision and the draft. The worker also asks for the ticket’s embedding, and then it saves everything. The last note matters for this course: when the answer has no text, the job fails, the ticket keeps no team, and nobody is told.
Where the answers come from: replayed and simulated
Section titled “Where the answers come from: replayed and simulated”In the scaling course, the simulated provider’s times were real, but its answers were one fixed sentence. That was fine for load tests. This course asks whether the answers are good, and a fixed sentence is never wrong in an interesting way.
The evaluation course sent the assistant’s requests to a real hosted model and kept every answer. That is 1,358 recorded calls: 679 with prompt v2 and 679 with prompt v3. Some tickets were sent more than once, so there are 542 different requests. The simulator now has these recordings. When it gets a request that was recorded, it sends back one of the recorded answers, after the recorded time. That is a replay: like a recording of a concert, the music is real, but it is played again at another time.

Text description of the diagram
The simulator makes a key from the request’s fields. These are the model, the messages (prompt, policy and the ticket’s text), the output schema and the token limit. If the key is one of the 542 recorded requests, the answer is replayed: a real model wrote it. If you write a ticket yourself, the key is new, and the simulator makes a simulated answer from a template. Its time, its token counts and how often it is cut off still come from the recordings.
To get replayed answers, you send practice tickets: the evaluation course’s 271 made-up tickets, with the labels that Grace’s team gave them. Three of them have only an attachment and no text, so 268 can be sent. No real customer wrote any of them.
What the recordings say about the two prompts:
| Prompt | Recorded calls | Answers without text | Median time | Slowest |
|---|---|---|---|---|
| v2 (live) | 679 | 1 (ticket T-65450, “spark plug”) | 2.95 s | 10.0 s |
| v3 (candidate) | 679 | 88 | 5.55 s | 12.1 s |
An answer without text is a call that used all its 1,000 tokens on the model’s hidden reasoning. It stopped before it wrote the JSON answer. The provider reports this as finish_reason: length. The worker cannot read a team or a decision from an empty answer. Keep the v2 line in mind: even the good prompt has one such answer, and a later module shows why that matters.
Set up the project
Section titled “Set up the project”You copy the snapshot start, check that it works, and then copy this module’s snapshot end-of-m01 over it.
-
Get the files of the course. If you have Git, clone the labs repository once, in
~/projects. If you have the clone already, rungit -C nextia-learning-labs pullinstead.Terminal window cd ~/projectsgit clone https://github.com/Nextia-Intelligence/nextia-learning-labs.gitWithout Git, download the ZIP file of the repository, and unzip it in
~/projects. Its folder is thennextia-learning-labs-main. Use that name in the next steps. -
If a folder
ticket-apiexists, rename it first. Then copy the snapshotstart, and make your.envand the API key file:Terminal window mv ticket-api ticket-api-scaling # only if the folder existscp -R nextia-learning-labs/C25/snapshots/start ticket-apicd ticket-apicp .env.example .envmkdir -p secrets && echo "local-practice-key" > secrets/api_key.txtTerminal window Rename-Item ticket-api ticket-api-scaling # only if the folder existsCopy-Item -Recurse nextia-learning-labs\C25\snapshots\start ticket-apicd ticket-apiCopy-Item .env.example .envNew-Item -ItemType Directory -Force secrets; Set-Content secrets\api_key.txt "local-practice-key" -
Open the folder in VS Code. In
.env, replacechange-me-local-onlywith a password of your own, in all three places. -
Start Docker Desktop. Then start PostgreSQL, Azurite and Valkey:
Terminal window docker compose up -d db azurite cache -
Make the virtual environment, install the packages, load the data and run the tests:
Terminal window python3 -m venv .venvsource .venv/bin/activatepython -m pip install -r requirements.txtpython -m scripts.loadpython -m pytestTerminal window python -m venv .venv.venv\Scripts\Activate.ps1python -m pip install -r requirements.txtpython -m scripts.loadpython -m pytestThe tests end with
176 passed, 1 deselected. This is the scaling course’s project, and it works. -
Copy the snapshot
end-of-m01over your project. It does not have a.envorsecrets/, so yours stay.Terminal window cp -R ../nextia-learning-labs/C25/snapshots/end-of-m01/. .Terminal window Copy-Item -Recurse -Force ..\nextia-learning-labs\C25\snapshots\end-of-m01\* .The snapshot also has the files of the next three lessons, so you copy only once in this module.
-
Apply the new migration and load the data again. The tables already have data, so add
--reset:Terminal window python -m scripts.load --resetapplied 015_triageDatabase is up to date (15 migrations).Loaded the small data in 0.6 s:customers 40tickets 200messages 331attachments 43documents 36ai_runs 294ticket_embeddings 20043 files uploaded to the object storage.3 messages have no ticket: they are in orphaned_messages.One migration is new:
015_triage. The small data is the same as before. -
Run the tests:
python -m pytest. Expect185 passed, 1 deselected, 9 more than before. The new tests check the triage step, the replay and theopstool.
What the new files do
Section titled “What the new files do”| File | What it does |
|---|---|
ticket_api/assistant.py |
The triage request, and the code that reads its answer. |
ticket_api/prompts/ |
Prompts v2 and v3, Grace’s policy and the output schema. |
migrations/015_triage.sql |
The task triage, the five teams, needs_human, finish_reason. |
simulator/replay.py, recorded_assistant.jsonl.gz |
The recorded answers, found by request key. |
scripts/practice.py, data/practice/ |
Sends practice tickets; saves their IDs in practice/sent.jsonl. |
ops/ |
The course’s ops tool: reads saved files, standard library only. |
operations/ |
The files of the next three lessons. |
One setting is new in .env.example: ASSISTANT_PROMPT=assistant-v2, the live prompt (the default, so your .env does not need it). It is the setting that Omar’s team changed last week.
Run it: three terminals and practice tickets
Section titled “Run it: three terminals and practice tickets”You run three services and send tickets from a fourth terminal. Activate the virtual environment in each terminal.
-
Terminal 1, the simulated provider. Leave it running.
Terminal window python -m simulatorSimulated AI provider on http://127.0.0.1:8300/v1 (mode normal). Its times and quota come from real recorded calls; its answers are simple. Stop it with Ctrl+C.The first line is still the scaling course’s. For practice tickets, “its answers are simple” is no longer true: they are replayed.
-
Terminal 2, the API. Leave it running too.
Terminal window fastapi dev -
Terminal 3, the worker. It takes the queued tickets and triages them.
Terminal window python -m ticket_api.workerWorker your-computer-46114: up to 4 jobs at a time. Stop it with Ctrl+C.The worker’s name is your computer’s name and the process number.
-
Terminal 4, practice tickets. Send 20 practice tickets, 2 each second:
Terminal window python -m scripts.practice --tickets 20 --rate 2Sent 20 practice tickets in 9.5 s: 202: 20Saved the ticket IDs in practice/sent.jsonl. The worker does their AI work; watch it withpython -m scripts.queue_watch
Every ticket got 202: the API accepted it and queued a job. In terminal 3, the worker logs one line per job, for example job 1: succeeded (attempt 1). Your times will differ.
Now look at the queue, as you did in the scaling course. Press Ctrl+C after a few lines:
python -m scripts.queue_watchThe author’s run, started right after the practice script:
time queued ready running oldest s done/min dead 0 8 8 4 3.7 8 0 1 6 6 4 3.7 10 0 2 6 6 4 4.7 10 0 3 6 6 4 5.7 10 0 4 3 3 4 5.2 13 0 5 3 3 4 6.2 13 0 6 2 2 4 6.7 14 0 7 2 2 4 7.7 14 0The worker runs 4 jobs at a time. Two tickets arrive each second and each takes about 3 seconds, so the queue grows a little, and then it empties. A few seconds later, done/min reaches 20.
Read one job’s result. The first ticket of a fresh load is T-500001, with job 1. On Windows, type curl.exe instead of curl.
curl http://127.0.0.1:8000/v1/jobs/1{"job_id":1,"ticket_id":"T-500001","state":"succeeded","attempts":1,"max_attempts":5,"created_at":"2026-10-11T07:52:30.687528Z","started_at":"2026-10-11T07:52:30.856745Z","finished_at":"2026-10-11T07:52:33.525167Z","last_error":null,"result":{"team":"delivery","priority":2,"needs_human":false,"draft_reply":"I'm sorry your fire pit arrived damaged. Please send us photos of the damage within 14 days of delivery. The team will send a replacement at no cost, or provide a full refund if a replacement is not in stock.","embedding_version":"embed-small-384-v1"}}The result has the assistant’s three outputs: the team delivery, needs_human: false (so priority 2), and a draft reply. A real model wrote that reply for that exact message.
Last, ask the simulator where its answers came from:
curl http://127.0.0.1:8300/admin/stats{"mode":"normal","in_flight":0,"max_in_flight":4,"calls":{"embed":{"200":20},"triage":{"200":20}},"tokens":46593,"triage_answers":{"replayed":20},"model_version":"gpt-6-luna-2026-09-22","simulated":true}triage_answers counts where the answers came from: all 20 were replayed. model_version is the version of the hosted model that wrote the recordings. Now send a ticket that you write yourself:
curl -X POST http://127.0.0.1:8000/v1/tickets -H "Content-Type: application/json" \ -d '{"customer_id": "C-0022", "subject": "Charged twice", "body": "Two payments for one order."}'On Windows, put it on one line without the \, and type curl.exe. A few seconds later, its job (job 21, after the 20 practice tickets) has a team and the template reply Thank you for your message. We will reply with the next steps soon., and the stats show "triage_answers":{"replayed":20,"simulated":1}. Nobody recorded that message, so its answer is simulated.
Stop the worker, the API and the simulator with Ctrl+C when you finish. You can also stop the containers: docker compose stop.
Read a saved week with the ops tool
Section titled “Read a saved week with the ops tool”You ran 20 tickets. Larkfield gets about 822 tickets a day. To see a week, you need a week of tickets, and a record of what happened to each one.
That record is telemetry: the records that a service writes about its own work, while it works. In Logs, metrics and traces, you add it to the service yourself. For now, you read telemetry that the course team saved. The team ran the same service, with the same recorded answers, through practice scenarios. Each scenario is a file of JSON lines: one record per line, about one event of one ticket.
The scenarios send 2 tickets a second, about 210 times Larkfield’s real average. So a week of tickets (5,754) ran in 48 minutes. The course counts in tickets, not in days, so the numbers stay true at real speed. The assistant’s times are the real recorded ones.
-
Copy the saved telemetry and the release files into your project’s
data/folder:Terminal window cp -R ../nextia-learning-labs/C25/data/telemetry ../nextia-learning-labs/C25/data/releases data/Terminal window Copy-Item -Recurse ..\nextia-learning-labs\C25\data\telemetry, ..\nextia-learning-labs\C25\data\releases data\Without Docker, a copy of the snapshot
end-of-m01and Python 3.12 are enough:opsneeds no packages. -
Read the normal week:
Terminal window python -m ops summary data/telemetry/normal-week.jsonl.gzRecords: 13,558 logs, 11,614 spans, 9,240 metric records, from +0.0 min to +48.0 minTicket requests: 5,754 (202: 5,754)Tickets triaged: 5,754 (ok: 5,750, no_answer: 4)Prompt versions: assistant-v2 5,754Where the answers come from: replayed 5,754 (100.00%)Sent to a person (needs_human): 1,446 (25.13%)Agents' reviews (delayed labels): 1,567; answers to questions: 470
Read it line by line:
- Records: logs, spans and metrics, explained in Logs, metrics and traces. Times are minutes from the start of the file.
- Ticket requests: the API accepted all 5,754 tickets.
- Tickets triaged: 4 answers had no text. All four are v2’s one “spark plug” recording, drawn four times.
- Prompt versions, where from: every ticket used v2, and every answer was replayed.
- Sent to a person: one ticket in four.
- Agents’ reviews: agents later checked 1,567 tickets. A later lesson uses them to measure quality.
Now read last week, the replay of the prompt v3 change:
python -m ops summary data/telemetry/release-full.jsonl.gzRecords: 5,907 logs, 46,987 spans, 3,440 metric records, from +0.0 min to +20.1 minTicket requests: 2,400 (202: 2,400)Tickets triaged: 2,400 (ok: 2,203, no_answer: 187, dead_letter: 10)Prompt versions: assistant-v3 1,798, assistant-v2 602Where the answers come from: replayed 2,390 (99.58%), None 10 (0.42%)Sent to a person (needs_human): 637 (26.54%)Agents' reviews (delayed labels): 1,051; answers to questions: 0Again, every ticket was accepted. But 187 tickets got no answer: 186 with v3, and v2’s one “spark plug” answer. Ten more became dead letters, the jobs that failed all 5 attempts, as in Delivery and retries. One v3 answer took 12.1 seconds, and the service’s timeout is 10 seconds, so every attempt failed. A dead letter never got an answer, so its “where from” is None. The 1,798 v3 tickets are about 2.2 days of Larkfield’s tickets, which matches “two days”.
The course team checked the empty answers against the practice tickets’ labels. Ten of them were tickets that needed a person. They were the frying pan (5 times), a parasol that fell toward a child (3 times), a parcel left at the wrong house, and a Spanish ticket about a lost order. Each of them waited, with no team, for nobody.
When to use a replay
Section titled “When to use a replay”Sam asks, “So is this the real assistant or not?”
Amira answers: “The answers are real. A real model wrote each one, for that exact request. The traffic, the timing and the incident are made up. So we can trust the replay for how the assistant answers. We cannot trust it for how customers behave.”
Use a replay when you need real model behaviour without the cost, the account and the changes of a live provider. Do not use it to judge new prompts or new tickets: those get simulated answers. It also repeats rare answers: the “spark plug” answer is one recording, drawn again and again in a long scenario. And it costs work: someone recorded the calls, and the recordings get old when the provider changes its model. So every number in this course says whether it is measured, replayed, simulated or an assumption.
Common mistakes
Section titled “Common mistakes”Common mistake
The worker is not running: the tickets wait
Symptom: scripts.practice prints 202 for every ticket, but queue_watch shows the queued column at 20, and the oldest s column grows by one each second. GET /v1/jobs/1 shows "state":"queued" and no result.
Cause: nothing takes the jobs. Terminal 3 is closed, or the worker stopped with an error.
Diagnose: the API accepts tickets without the worker, by design. That is the queue from the scaling course. So a full queue with no errors means a missing worker.
Fix: start python -m ticket_api.worker in terminal 3. It takes the 20 jobs, and the queue empties in a few seconds. This is also your first view of this course’s problem: every ticket is accepted while no customer gets an answer.
Common mistake
ops: no file
Symptom:
ops summary: no file data/telemetry/normal-week.jsonlCause: the path is wrong. Here the .gz is missing. The command also fails like this if you run it from another folder, or if you did not copy the saved telemetry.
Fix: run ops from the project folder, and check the name with ls data/telemetry (Windows: dir data\telemetry). The ops tool reads .jsonl and .jsonl.gz files.
Reset. python -m scripts.load --reset loads the data again, and new tickets start at T-500001 again. practice/sent.jsonl grows each time you send tickets; delete the practice folder to start it again. If your project is broken, copy the snapshot end-of-m01 and keep your .env and secrets/, as the snapshots README shows.
Knowledge check
Section titled “Knowledge check”Check your understanding
A practice ticket and a ticket that you write yourself both get an answer from the simulated provider. What is the difference between the two answers, and which one can you use to judge the assistant's quality?
Show the answer
The practice ticket’s request is one of the 542 recorded requests, so its answer is replayed: a real model wrote that text, with its real tokens, time and finish reason. Your own ticket’s request is new, so its answer is simulated: a template text, with times, tokens and cut-offs drawn from the recordings. Only the replayed answer says anything about the assistant’s quality. curl http://127.0.0.1:8300/admin/stats counts both kinds in triage_answers.
Does your answer have the main points of ours?
Sign in and enroll in the course to save your answers. Every check counts toward the certificate.
Check your understanding
In the summary of last week, every one of the 2,400 tickets got a 202. Explain why that number did not show the problem.
Show the answer
The 202 means that the API saved the ticket and queued its job. The AI work happens later, in the worker. With prompt v3, 186 answers had no text and 10 tickets became dead letters. With v2’s one empty answer, 197 tickets got no team, no decision and no draft. The API never saw that: it had already answered. A number about accepted requests measures only the first step of the customer’s journey.
Does your answer have the main points of ours?
Sign in and enroll in the course to save your answers. Every check counts toward the certificate.
Check your understanding
Practical check: show that your setup works. What do the tests, the practice script and the simulator's stats print?
Show the answer
python -m pytest ends with 185 passed, 1 deselected. python -m scripts.practice --tickets 20 --rate 2 prints Sent 20 practice tickets with 202: 20. After the worker has taken them, curl http://127.0.0.1:8300/admin/stats shows "triage_answers":{"replayed":20}: every answer was a real recording. Without Docker, python -m ops summary data/telemetry/normal-week.jsonl.gz prints Ticket requests: 5,754 (202: 5,754) and Tickets triaged: 5,754 (ok: 5,750, no_answer: 4).
Does your answer have the main points of ours?
Sign in and enroll in the course to save your answers. Every check counts toward the certificate.
Case studies in this course
At the end of the course, you use what you learn on a realistic project, from the data to the recommendation. Complete at least one for the certificate; the others are optional.
- Monitor a model on public data that changesTrain a simple model on early months of a public, time-stamped dataset, then build its drift and delayed-label monitor month by month, and say what the monitor can and cannot prove.
- Post-incident review of a public outageRebuild the timeline, detection, mitigation and preventive actions of a published provider incident report in the course's runbook and review format.
Recap
- The ticket service is live. One triage request per ticket gives the team, whether a person must handle it, and a draft. It is the evaluation course’s assistant, prompt v2.
- The simulated provider replays real recorded answers for the 268 practice tickets, and simulates answers for any other text. Prompt v2 has 1 answer without text in 679 recordings; prompt v3 has 88.
- Telemetry is the record that a service writes about its own work.
python -m ops summaryreads a saved file: the normal week had 5,754 tickets, all accepted, 4 without an answer. - Last week, in a practice replay, every ticket was accepted, but 197 got no answer, and 10 of them needed a person. MLOps and LLMOps are the work of seeing and preventing this.
Next, you list everything that the service depends on, each part’s version, and the first sign that it fails.
Next: What is operated