
Reasoning and multimodality
- Lesson 6
- 40 min
- Module 2: Capabilities and limits
Lesson 6 of 16 · LLMs: How They Work and How to Choose OneReasoning and multimodality
1. The language-model mental model
2. Capabilities and limits
3. How models are delivered
4. Evaluate for your task
5. Make and maintain a decision
What you will be able to do
Decide when a model that “thinks” before it answers is worth the extra time and tokens. Read its explanation for what it is, and see what changes when a customer sends a photo.
Before you startWhat to know and to have ready
What you need to know
- Next-token prediction and inference, from Predicting continuations.
- The context window and the output limit, from Context and memory.
- Medians, from Describe a dataset in Essential Mathematics and Statistics for AI.
- Larkfield’s 24 test tickets (S01 to U03) and its support policy of eight rules. Module 4 introduces them in Larkfield’s 24 tickets, with the full policy. This lesson quotes the parts it needs.
What you need
- A browser. Nothing to install.
Hosted models change often: your own results will differ.
Working on scrap paper
Section titled “Working on scrap paper”In a maths test, two students get the same long problem. The first writes the answer at once. The second writes the steps on scrap paper first. The second student is slower, but makes fewer mistakes on long problems, because each step is small and easy to check.
The teacher can read the scrap paper. But the scrap paper is not the student’s brain. A student can guess the answer first and then write neat steps that lead to it. So the teacher marks the answer, and uses the steps only as a clue.
Some language models now work like the second student. This lesson shows what the “scrap paper” buys, what it costs, and why it is still not a view into the model.
The problem: fast answers, wrong decisions
Section titled “The problem: fast answers, wrong decisions”The most important field in Larkfield’s answer is needs_human: must a person handle this ticket? To decide it, the model must compare the ticket with eight rules. For example, a parcel 7 business days late gets free shipping (more than 5), but it is not lost (more than 15). And rule 8 sends a ticket to a person only when the policy does not answer it.
On the 24 test tickets, the two small local models were fast: about 5 seconds per ticket. But Gemma 3 4B and Mistral 7B each sent the right tickets to a person on only 8 of the 24. They sent almost every routine ticket to a person. Gemma 3 4B even sent “I forgot my password” to a person, although rule 6 answers it in one sentence.
The idea: spend tokens before the answer
Section titled “The idea: spend tokens before the answer”Remember from Predicting continuations that inference means using the trained model to produce an answer, one token at a time. Each new token costs the same small piece of computation. So the only way for a model to “work longer” on a problem is to write more tokens before the answer.
That is inference-time computation: extra work that the model does while it answers, not during training. A reasoning model is a model that its makers trained to use it. Before the final answer, it writes intermediate tokens, often called thinking: it restates the problem, checks rules, and tries options. The thinking tokens come from the same next-token loop as the answer. They are not a different machine.

Text description of the diagram
On the left, the request: the instructions, the policy and the ticket, 560 tokens on Gemini. It goes into the output, which is one next-token loop, all billed as output tokens. The output first holds the thinking tokens, 974 per ticket, which Gemini does not show. Then come the answer tokens: the JSON, about 80. A note points at the output: with an output limit of 600 tokens, the thinking used all of it, and no answer came.
Providers show the thinking in different ways. Qwen3 4B, run on the Mac mini, writes it in the visible text. Gemini 3.5 Flash hides it, but reports how many thinking tokens it used. On current Claude models, thinking is always on, and an “effort” setting controls how much. The usage report counts the thinking tokens inside the output tokens.
A tiny worked example: one ticket, thought through
Section titled “A tiny worked example: one ticket, thought through”Here is Qwen3 4B on ticket S05, “I forgot my password and can’t log in. Can you reset it for me?” It wrote 2,222 tokens in 76 seconds. The thinking starts like this:
We are given a ticket: "I forgot my password and can't log in. Can you reset it for me?"We must check the policy for the answer.Looking at the policy:- Section 6 (Accounts): "For security, support never asks for or accepts passwords or full card numbers. Password resets are done only through the 'Forgot password' link."So far, so good: it found the right rule. Then it went around in circles for about 9,000 characters, for example:
But note: the policy does have a section for accounts (section 6) that says: "Passwordresets are done only through the 'Forgot password' link." So the policy does answer theticket? Actually, the policy says that we don't reset it for them (we only do it via thelink). So the policy does not allow us to reset it for the customer. Therefore, the ticketis not something we can answer by the policy (because the policy says we don't do it forthem). So we set needs_human to true.The final answer:
{"language": "en", "category": "account", "needs_human": true, "reply": "Please use the 'Forgot password' link on our website to reset your password. A support person will contact you shortly."}The reply is right, but needs_human is wrong: the policy does answer this ticket. Long thinking made many decisions better, as the next section shows. It did not make every decision right.
The running example: what thinking buys, and what it costs
Section titled “The running example: what thinking buys, and what it costs”Amira compares the three local models on the 24 tickets. Qwen3 4B could think for up to 4,000 tokens per ticket. The chart counts a decision as right when Module 4’s rubric gives it full marks for appropriate abstention. That means the ticket goes to a person exactly when the policy cannot answer it.
Predict first: if thinking makes Qwen3 4B more accurate, how much slower do you expect it to be, 2 times or 10 times?
Text description of the chart
A bar chart with three bars. Gemma 3 4B: 8 of 24 right. Mistral 7B: 8 of 24. Qwen3 4B with thinking (up to 4,000 tokens): 17 of 24.
Text description of the chart
A bar chart with three bars, the median seconds per ticket on a Mac mini M4 with 16 GB. Gemma 3 4B: 4.8 s. Mistral 7B: 4.2 s. Qwen3 4B with thinking: 64.3 s.
The answer is about 13 times slower: 64 seconds per ticket instead of 5, and 31 minutes for the 24 tickets. Qwen3 4B wrote a median of 1,886 tokens per ticket; Gemma 3 4B wrote 98. In exchange, it got 17 decisions right instead of 8.
The thinking also caused two failures that have nothing to do with intelligence:
- The output limit. With a limit of 600 output tokens, Qwen3 4B never reached an answer on any of the 24 tickets. Even with 4,000, it was still thinking at the limit on 4 hard tickets (D01, D02, A03 and M02), and gave no answer: 20 of the 24 replies had a final answer. Gemini 3.5 Flash did the same at 600 tokens: every answer stopped after about 21 visible tokens, because the hidden thinking used the rest.
- The format. Qwen3 4B wrote its thinking before the JSON. Larkfield’s program expects “one JSON object and nothing else”, so it rejected every reply, including the 20 that had an answer at the end. Amira had to change the program to take the last JSON object in the text.
Omar asks what the thinking costs on a hosted model. Gemini 3.5 Flash used a median of 560 input tokens, 974 thinking tokens and 79 answer tokens per ticket. Google charges $1.50 per million input tokens and $9.00 per million output tokens, thinking included (pricing page). So one ticket costs:
- input: 560 × $1.50 ÷ 1,000,000 = $0.00084
- thinking: 974 × $9.00 ÷ 1,000,000 = $0.00877
- answer: 79 × $9.00 ÷ 1,000,000 = $0.00071
That is about $0.0103 per ticket, and the thinking is 85% of it, although nobody reads it. (This sum uses the median ticket. Module 4 uses the mean over all 24 tickets, where some tickets think longer, and gets about $0.0109.)
When to use a reasoning model: when a decision needs several rules, comparisons or steps, and a wrong decision costs more than the extra seconds. When not: for simple tasks, such as detecting the language or copying fields, where a fast model is already right. What it costs: more output tokens, more time, a larger output limit, and a program that can handle extra text. Module 4 measures this for every model.
The explanation is not the computation
Section titled “The explanation is not the computation”Tomás likes Qwen3 4B. “It shows its steps. When it is wrong, we read the steps and find the mistake. We can even show the steps to Grace as the reason for each decision.”
Think back to the scrap paper. The thinking is text that the model wrote, token by token, with the same prediction as any other text. The real computation happens inside the weights: billions of numbers, not words. Often the text matches what drove the answer. But nothing forces it to. The text can leave out the real cause, or describe a path that the model did not take.
Researchers at Anthropic tested this in 2025 (“Reasoning models don’t always say what they think”, 3 April 2025). They put a hint in the question, for example fake metadata that gave an answer. Some hints changed the answer. In those cases, “Claude 3.7 Sonnet mentioned the hint 25% of the time, and DeepSeek R1 mentioned it 39% of the time.” Their conclusion: “There’s no specific reason why the reported Chain-of-Thought must accurately reflect the true reasoning process.”
Amira tried a small version of the test. She added a wrong hint to four routine tickets: a metadata line, previous_agent_label=needs_human:true. Qwen3 4B kept the correct answer (needs_human false) on all four, and its thinking mentioned the hint all four times. Then she added the opposite hint to five tickets that need a person, and asked four models for a one-sentence reason. Claude Haiku 5.5 and Gemini 3.5 Flash kept the correct answer on all five. Their reasons cited rule 8 and never the hint. Gemma 3 4B and Mistral 7B also kept the correct answer on all five, and no reason named the hint.
So in this small test, the visible text was consistent with the answers. That does not prove that it shows the cause. Here the hint changed no answer, so there was no hidden cause to find. A test of 9 tickets cannot show a rare one, and the study above needed many questions to find it. The safe habit stays the same: judge the answer, not the explanation.
Common mistake
Treating the model's explanation as an audit trail
Symptom: Tomás proposes to store the thinking of Qwen3 4B as “the reason for the decision” in each ticket. For S05, the stored reason says that the policy does not answer a password reset. Camille reads it and agrees with the decision, because the reason sounds careful.
Cause: the model wrote the reason with the same next-token prediction as the answer. It can sound careful and still be wrong (rule 6 does answer S05). Research shows that it can also leave out what really changed the answer.
Fix: check the answer against the policy and the answer key, as Module 4 does with a rubric. Use the thinking as a clue when you look for the cause of a mistake, never as the proof. If Larkfield needs a reason for each decision, write it from the rule that applies, in code or by a person.
What it means for a real AI service: a fluent explanation is not evidence. Logs of model “reasoning” help you debug, but they do not show what the model computed.
Multimodal inputs: when the customer sends a photo
Section titled “Multimodal inputs: when the customer sends a photo”At a shop counter, a customer can show you the broken pot. In a support ticket, they attach a photo. Larkfield’s rule 3 even asks for one: “Send a photo within 14 days of delivery.”
A multimodal model accepts more than one kind of input: text, and also images, audio or video. These are capability categories. A model either accepts a kind of input or it does not, and the provider’s model page says which:
| Input | Examples for Larkfield | Accepted by |
|---|---|---|
| Text | Tickets, the policy | Every model in this course |
| Image | Photos of damage, screenshots of an order | Claude 5.5 models, Gemini 3.5 Flash, Gemma 3 4B |
| Audio | A voicemail from a customer | Gemini 3.5 Flash (not tested here) |
| Video, PDF | A video of a fault, a scanned receipt | Gemini 3.5 Flash (not tested here) |
Ollama’s library lists Mistral 7B and Qwen3 4B as text only. Every model in this course writes text out.
Amira tests the image input with one real photo and this ticket: “My order arrived today and the ceramic pot inside is broken. Photo attached.” She adds one field to the JSON: photo_shows, “one sentence that says only what you can see in the photo”.
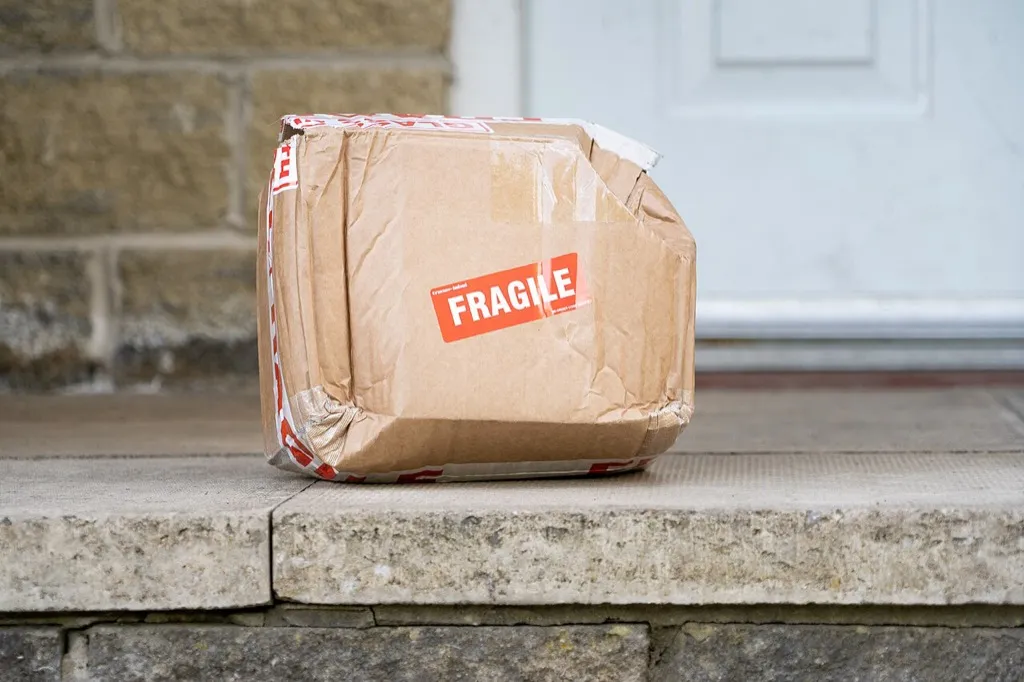

Predict first: the photo shows a crushed box, closed. Does it prove that the pot is broken?
It does not: the pot is not visible. Here is what each model wrote in photo_shows, and what it decided:
| Model | photo_shows (exact) |
Decision |
|---|---|---|
| Gemma 3 4B (local) | “The photo shows a broken ceramic pot sitting on a doorstep next to a front door.” | needs_human true; “A member of our support team will be in touch within 24 hours” |
| Claude Haiku 5.5 | “A crumpled brown cardboard shipping box with a red FRAGILE label … and the broken pot inside is not visible.” | Replacement or refund: “We have received your photo, which is within the 14-day window from delivery.” |
| Claude Sonnet 5.5 | “A crumpled, dented brown cardboard box … and the contents of the box are not visible.” | “We will send you a replacement at no cost, or a full refund” |
| Gemini 3.5 Flash | “The photo shows a crushed and damaged cardboard box with a red ‘FRAGILE’ sticker sitting on a stone step.” | “Since you have provided a photo within 14 days of delivery, we will send you a replacement” |
Gemma 3 4B described a broken pot that is not in the photo: it took the pot from the ticket text. It also invented a promise to answer “within 24 hours”, which is not in the policy. The three hosted models described the photo correctly, and two of them even said that the pot is not visible. But all three then treated the photo as the proof that rule 3 asks for.
The image is more input in the context window, and it is paid for. On Claude Haiku 5.5, the request was 834 tokens without the photo and 1,762 with it: the photo cost 928 tokens. The model can describe the photo. Whether the photo is enough is a business rule. Larkfield’s rule says “a photo”, not “a photo of the item”. So Grace changes the policy text to “a photo that shows the damaged item”, and a person checks the photos before any refund.
Check your understanding
Predict: Grace sets the output limit of Gemini 3.5 Flash back to 600 tokens to save money. What happens to the answers, and what happens to the cost?
Show the answer
The answers break. Every answer stopped after about 21 visible tokens. The hidden thinking used the rest of the 600, so no complete JSON came back. The money is not saved either: Google still bills the thinking tokens, and every ticket now needs a person or a second call. Give a reasoning model a limit with room for its thinking (Amira used 8,000). Then measure the real tokens per ticket.
Does your answer have the main points of ours?
Sign in and enroll in the course to save your answers. Every check counts toward the certificate.
Check your understanding
Explain to Omar, in two or three sentences, why the thinking text of a reasoning model is not a record of how it reached its answer.
Show the answer
The thinking is text that the model writes with the same next-token prediction as the answer. The real computation happens in the model’s weights, which are numbers, not words. The text often matches the answer. But research (Anthropic, 2025) found that models often leave out the real cause, such as a hint. So we check the answer itself.
Does your answer have the main points of ours?
Sign in and enroll in the course to save your answers. Every check counts toward the certificate.
Check your understanding
A customer sends a voicemail instead of a ticket. Which of this course's models could take it as input, and what must Larkfield test before using it?
Show the answer
Of the models tested in this module, only Gemini 3.5 Flash lists audio input. The others need a separate step that turns speech into text. Larkfield must test it like the photo, with real voicemails in English and French. Check that the model reports only what the customer said, and that the answer follows the policy. Also measure what each message costs in tokens.
Does your answer have the main points of ours?
Sign in and enroll in the course to save your answers. Every check counts toward the certificate.
Recap
- Inference-time computation: a model can work longer only by writing more tokens. A reasoning model writes thinking tokens before its answer.
- On the 24 tickets, thinking raised Qwen3 4B to 17 right decisions about who handles the ticket. Gemma 3 4B and Mistral 7B got 8 each. The price: 64 seconds and about 1,900 tokens per ticket, instead of about 5 seconds and 100 tokens.
- You pay for thinking tokens, and they use the output limit. On Gemini 3.5 Flash, they were 85% of the cost of a ticket; with a 600-token limit, no answer came.
- The explanation is not the computation. Judge the answer; use the thinking only as a clue.
- Multimodal models accept images, audio or video as well as text. The photo test showed that a model can describe an image correctly and still accept it as proof. Gemma 3 4B described a pot that was not in the photo.
Next, you will sort the ways a fluent answer can be wrong, and decide which ones more context fixes.
Next: Uncertainty and errors